Does Claude feel dumber than it did last week?
It's not just you. Many AI power users believe new models are secretly nerfed after launch to cope with demand and cut costs.
Now someone measured what's really happening.
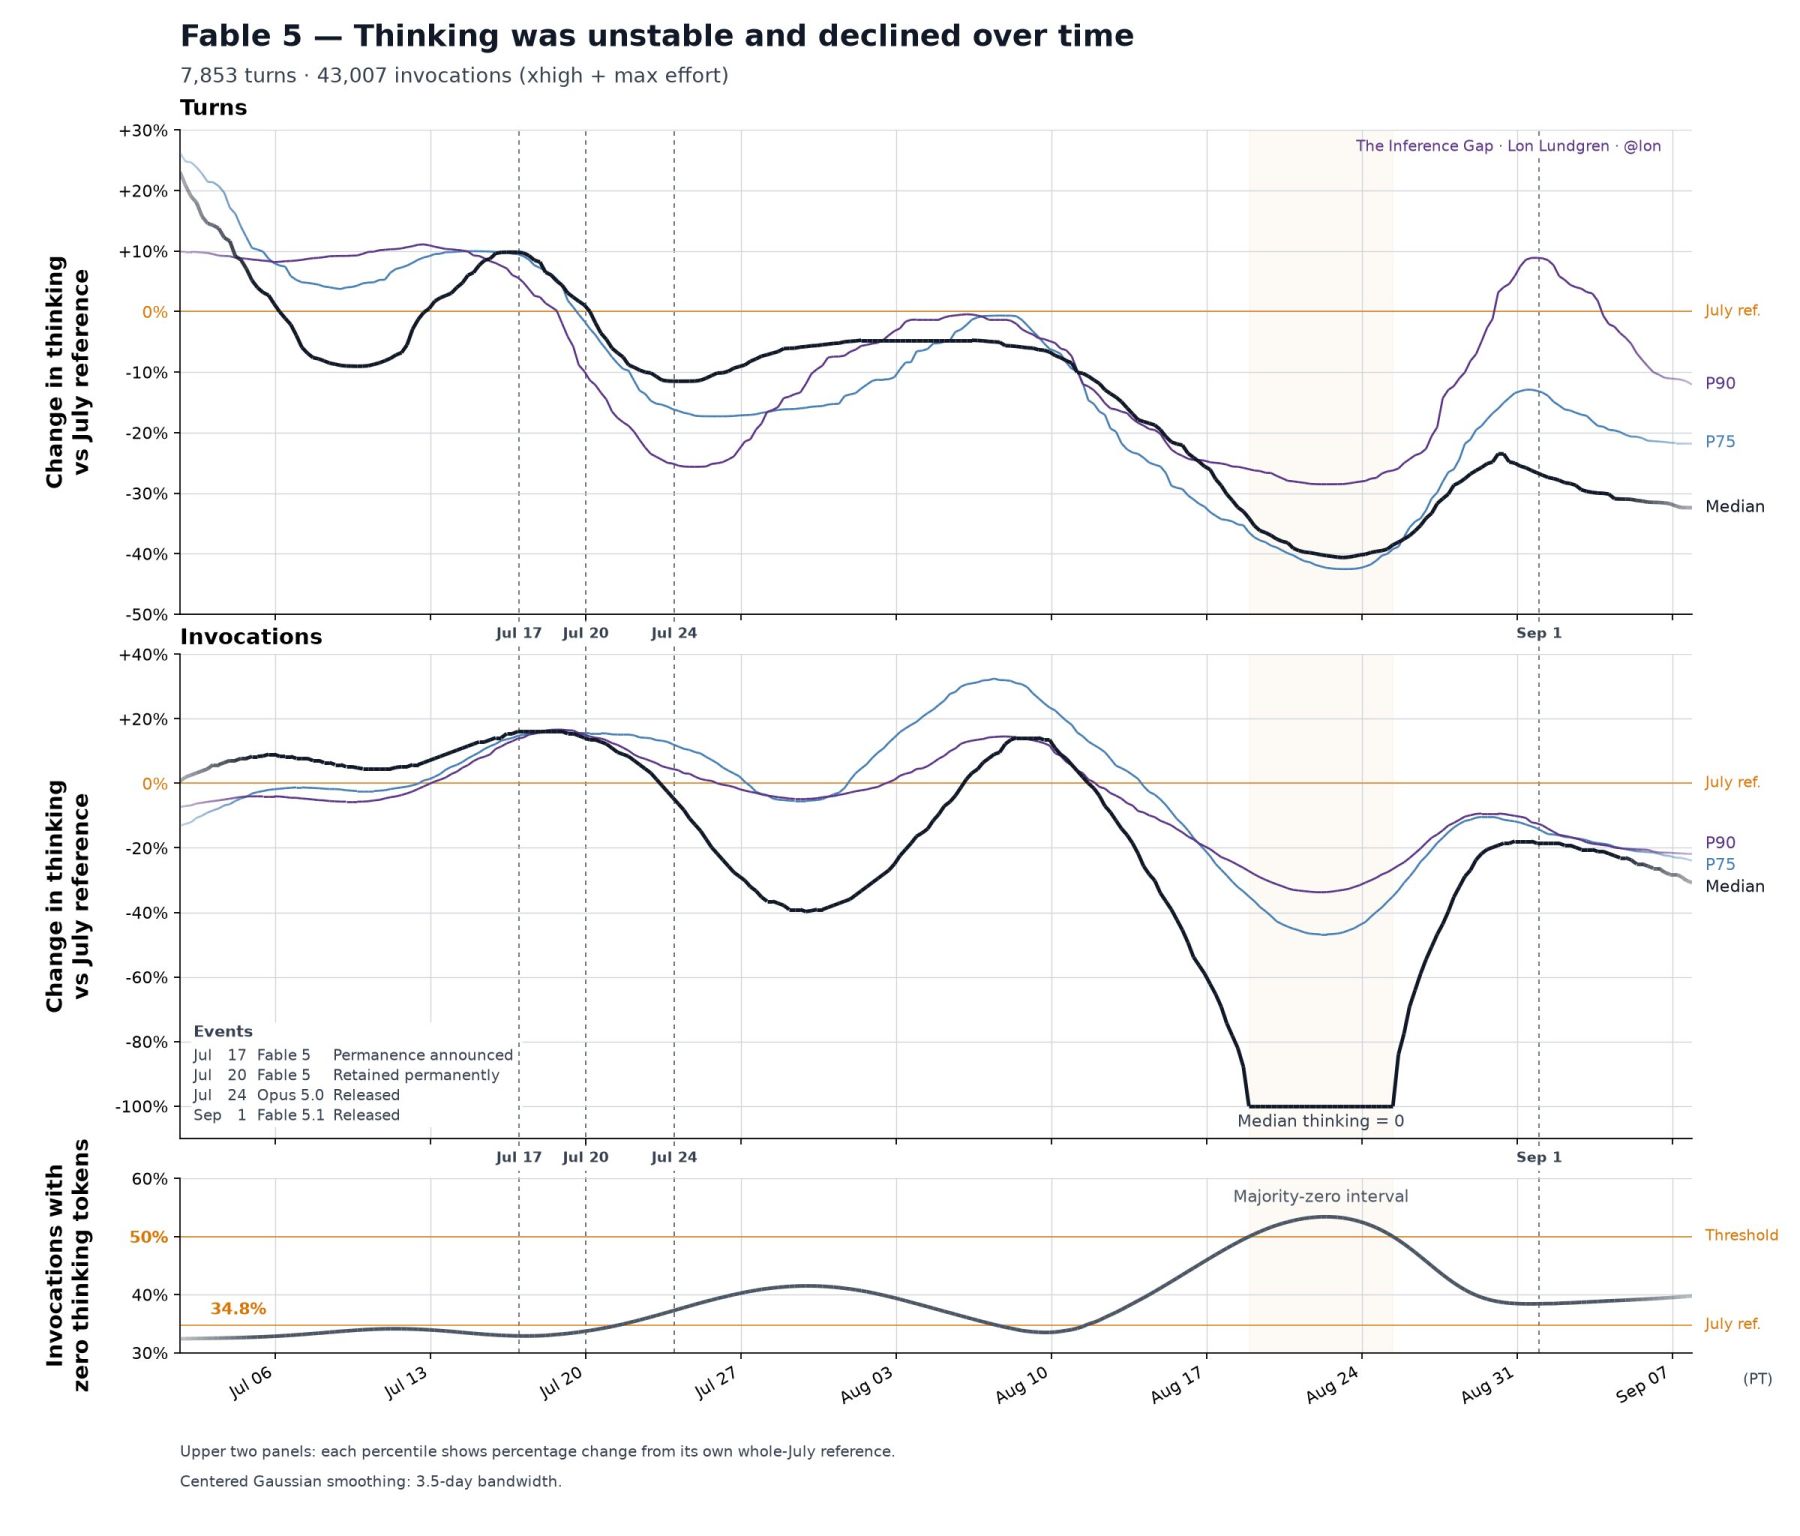
An ex-Amazon and Microsoft researcher spent six weeks logging 43,000 calls to Anthropic's Fable 5 at its highest effort settings.
He didn’t find evidence that the model had changed.
Instead, he found something much more interesting: thinking effort fell by up to half from July to August, and fluctuated significantly week to week.
Worse: the benchmarks Anthropic advertises for Fable were run with roughly 200x more thinking than the typical call he measured.
What does this mean? Personally, it confirms something I already believed: you cannot trust an agent you aren't measuring and evaluating. For software development, that means a strong QA process for everything the model touches.
Source: @Lon on X